Home / Services / GPU Full-Stack Delivery

GPU Full-Stack Delivery

From bare racks to running GPU clusters — deployment, orchestration and validated handover in one engagement.
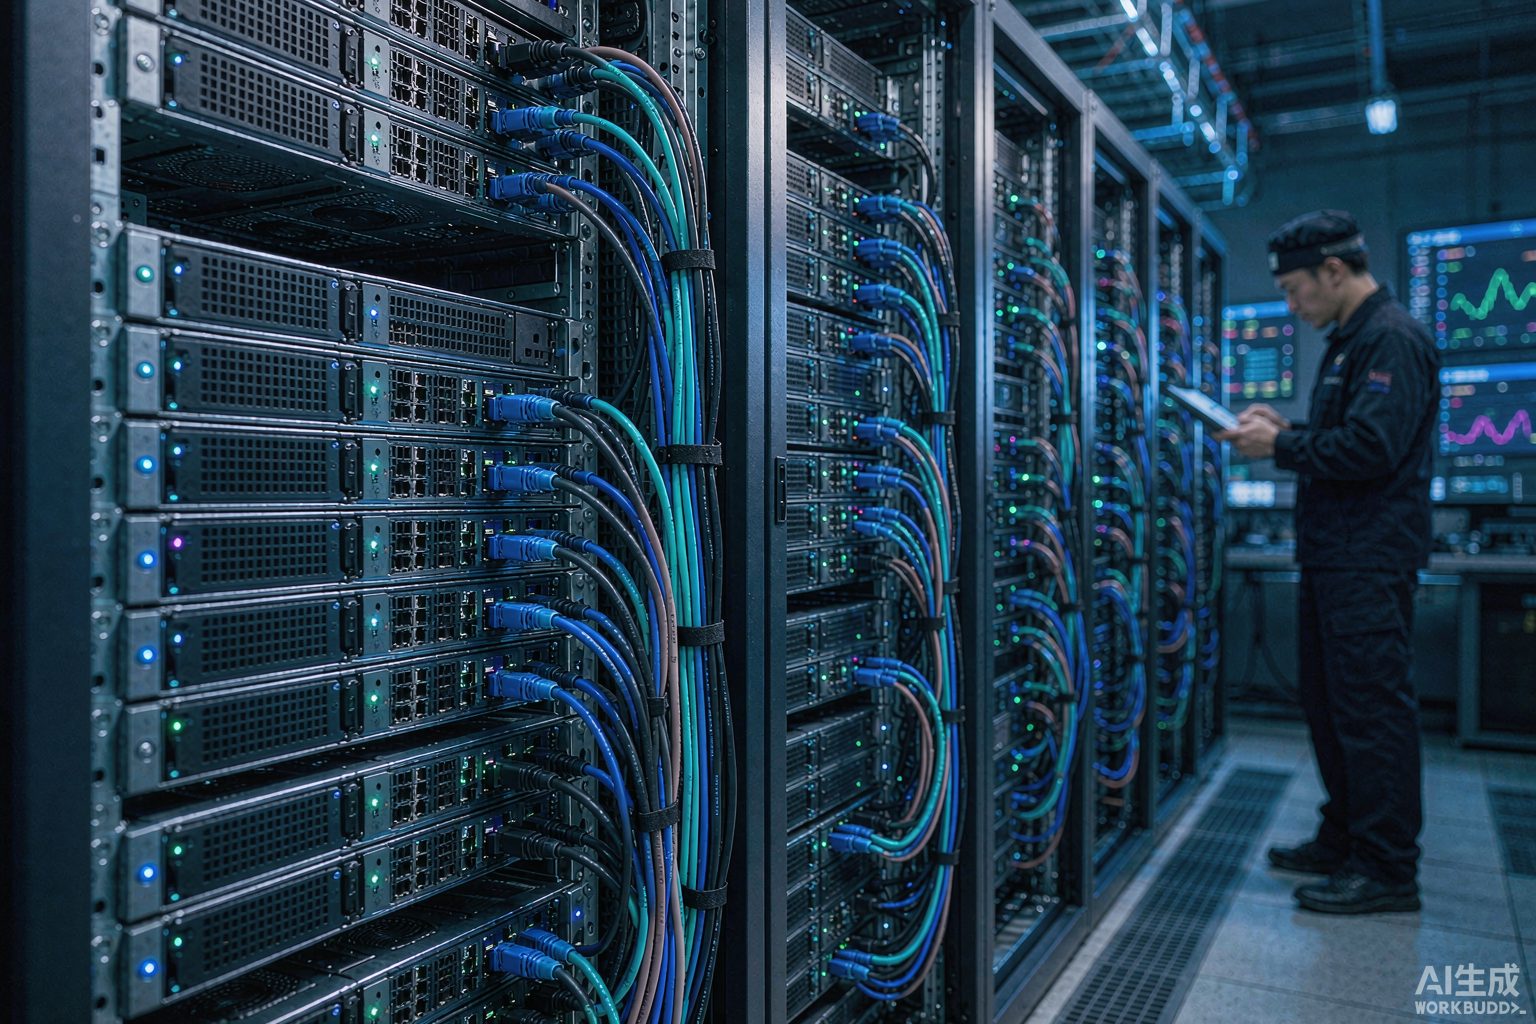
Bare metal → AI-readyInfiniBand · RoCEValidated handover

How we deliver

Five steps to your first training job.

One team takes the cluster from crates to benchmarks.

1

Rack & Stack

Install, power-on, burn-in

2

Fabric

InfiniBand / RoCE cabling

3

Virtualize

Partitioning & K8s scheduling

4

AI Stack

Drivers, firmware, runtimes

5

Handover

Benchmarks & training

Included

Every detail covered.

Physical, network and platform layers — delivered as one package.

⚡

Power-On & Burn-In

High-density racks, stress tested

🕸️

Compute Fabric

IB / RoCE built and verified

🧩

GPU Partitioning

Multi-tenant, K8s-native

🛠️

Stack Enablement

Drivers, CUDA, serving runtimes

📊

Benchmarking

NCCL, throughput, acceptance

📈

Monitoring Hookup

Dashboards from day one

🎓

Team Training

Handover sessions for your ops

🔁

Post-Go-Live Support

SLA-backed after handover

1End-to-end package
IB / RoCEFabric delivered
Day 1Training-job ready
SLABacked support
Reference stack

One stack, three layers, delivered end to end.

Layer 01AI Developer Ecosystem
PyTorchTensorFlowRayvLLM JupyterMLflowWeights & BiasesAirflow
Layer 02Control Plane
ProjectsUsersQuotaSSO / LDAP Multi-GPUMulti-NodePartitioningBatch Jobs
Layer 03Infrastructure Cluster
NVIDIAAMDBeeGFSCeph / NFS InfiniBandRoCE FabricLiquid Cooling
Detailed scope / 02

What we deliver, at a glance.

Pillar 01

GPU Cluster Deployment

  • Rack & stack, unboxing, power-on and burn-in
  • High-density copper / fiber structured cabling
  • InfiniBand / RoCE compute fabric build-out
  • Firmware baseline & BOM-level asset registration
Pillar 02

Virtualization & Orchestration

  • Multi-tenant GPU partitioning with strict isolation
  • Kubernetes-native scheduling for training & inference
  • Live utilization dashboards & quota enforcement
  • SSO / LDAP-grade access across the whole estate
Pillar 03

AI Stack Enablement

  • CUDA drivers, firmware & lifecycle upgrade planning
  • First-class support for PyTorch, TensorFlow, Ray, vLLM
  • Storage integration — BeeGFS, Ceph / NFS parallel filesystems
  • Observability & job-level monitoring integration
Pillar 04

Validation & Handover

  • Full-fabric stress testing & performance benchmarking
  • Acceptance test reports against agreed KPIs
  • Runbooks, documentation & as-built records
  • Handover training for your operations team

Tell us your cluster spec — we'll deliver it running.

Share GPU model, scale and timeline — get a phased delivery plan.
Get a Delivery Plan →